PromptPlayground
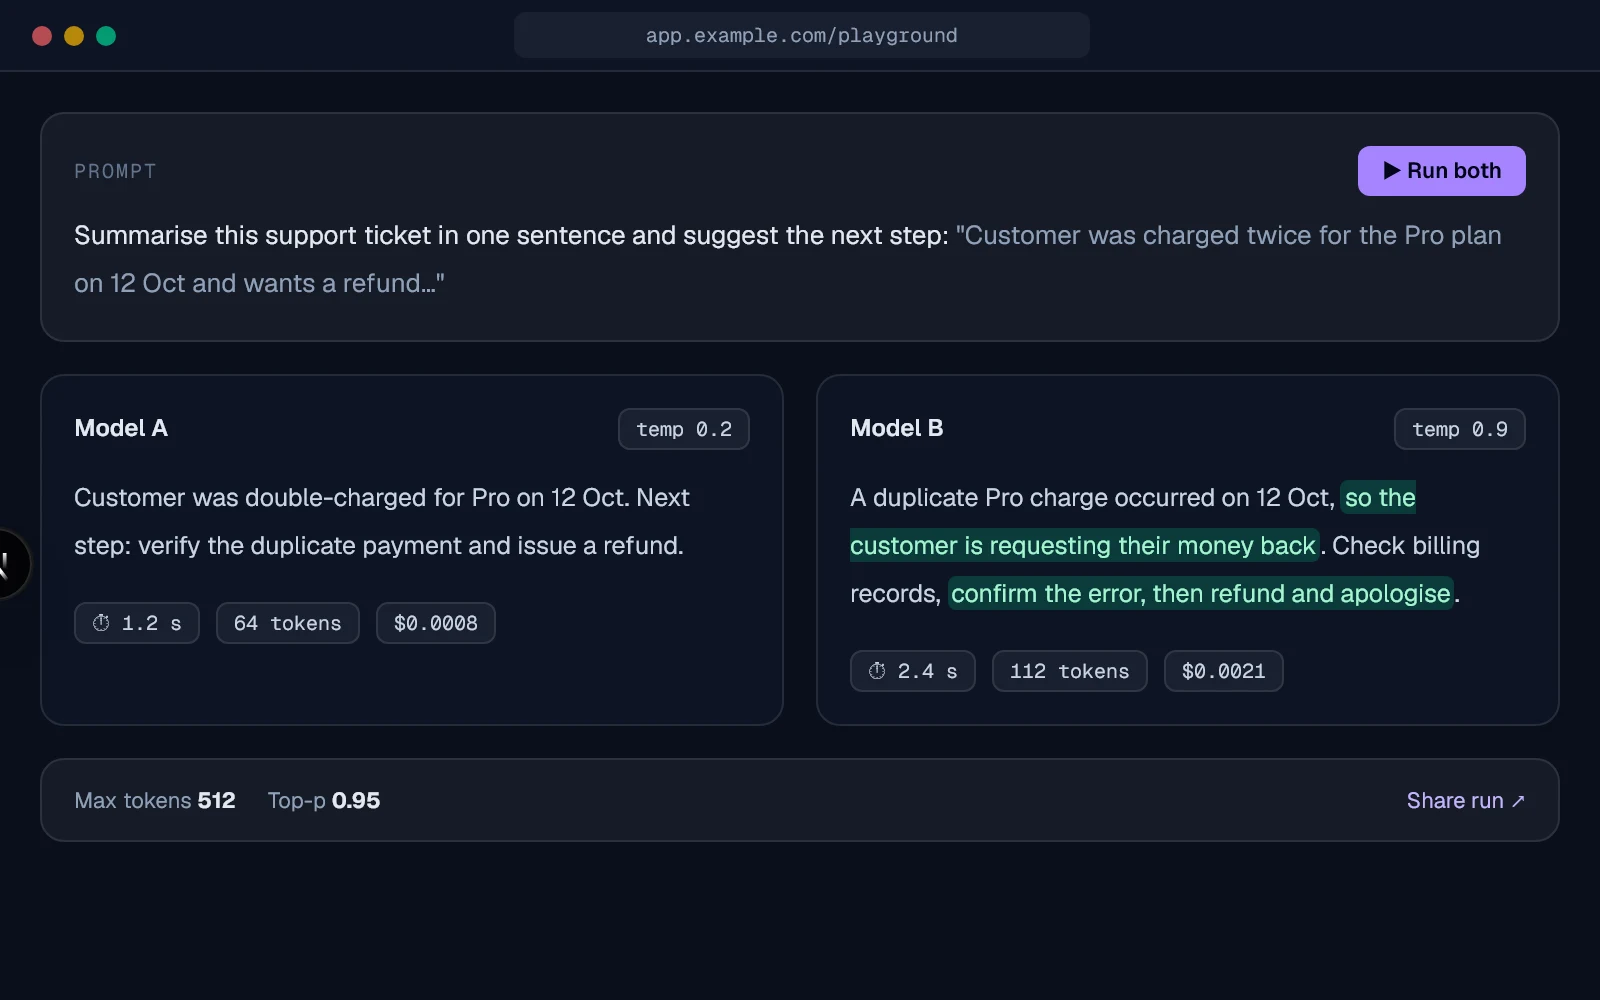
Side-by-side prompt and model comparison with parameter controls and shareable runs.
- Multi-model
- Diff view
- TypeScript
 AI-02
Illustrative preview of the intended interface.
Overview
What it solves
The problem
Comparing prompts and models usually means copy-pasting between tabs, losing parameters and eyeballing the differences.
The approach
PromptPlayground runs one prompt against several models side by side with shared parameters, highlighted differences and shareable runs.
Features
Key features
- 01
Side-by-side runs
Send the same prompt to multiple models at once and watch the answers stream in parallel.
- 02
Parameter controls
Temperature, max tokens and top-p per model, saved with every run.
- 03
Word-level diff
Differences between outputs are highlighted so you can see what changed, not just that it did.
- 04
Shareable runs
A run captures prompt, settings and outputs behind a single link.
Under the hood
How it works
- 1
Write
Compose the prompt and any variables.
- 2
Configure
Pick models and set parameters for each.
- 3
Run
Requests fire in parallel and stream back independently.
- 4
Compare
Review diffs, latency and cost, then share or save the run.
See it
Demo
Walkthrough video coming soon
A short screen recording will appear here.
Developer experience
Usage
Planned API — this shows the intended developer experience and may change as the component is built.
<PromptPlayground
  models={["model-a", "model-b"]}
  defaultParams={{ temperature: 0.2, maxTokens: 512 }}
  onRun={(run) => saveRun(run)}
/>
AI Interfaces
Metrics captured per run
Enough detail to reproduce a run and judge it fairly.
| Metric | What it shows |
|---|---|
| Latency | Time to first token and total completion time. |
| Tokens | Prompt and completion token counts. |
| Cost | Estimated from the model's token pricing. |
| Diff | Word-level differences between outputs. |
| Parameters | Exact settings, so any run can be repeated. |
Roadmap
Status & stack
Build progress
- Design & API — in progress
- Build — not started
- Accessibility & performance testing — not started
- Demo & write-up — not started
Tech stack
- React 19
- TypeScript
- Server-Sent Events
- Zod
- Tailwind CSS
Related research
- AI Interfaces4 min read
Building a streaming chat UI that doesn't jank
Token-by-token rendering, scroll behaviour and abort handling — the patterns that keep an LLM chat feeling instant.
- Streaming
- React 19
- UX
Read the note
More in AI Interfaces
 AI-01In progress
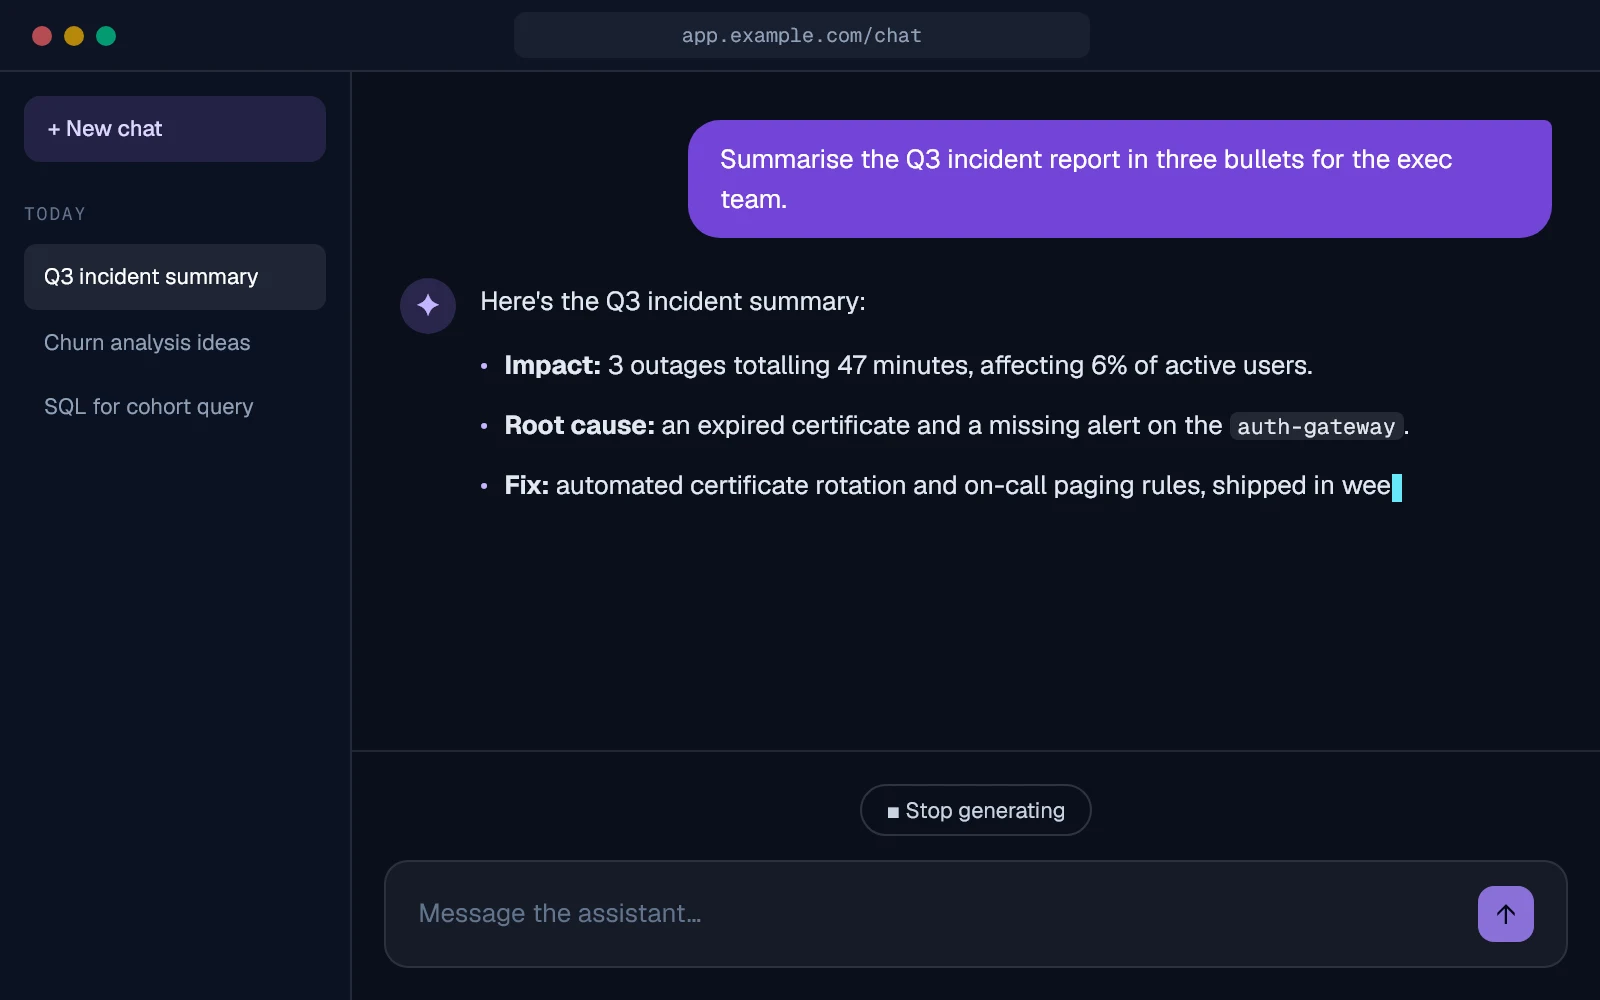
StreamingChat
Token-by-token chat UI with markdown rendering, abort, retry and optimistic message state.
- SSE
- Markdown
- React 19
 AI-03Planned
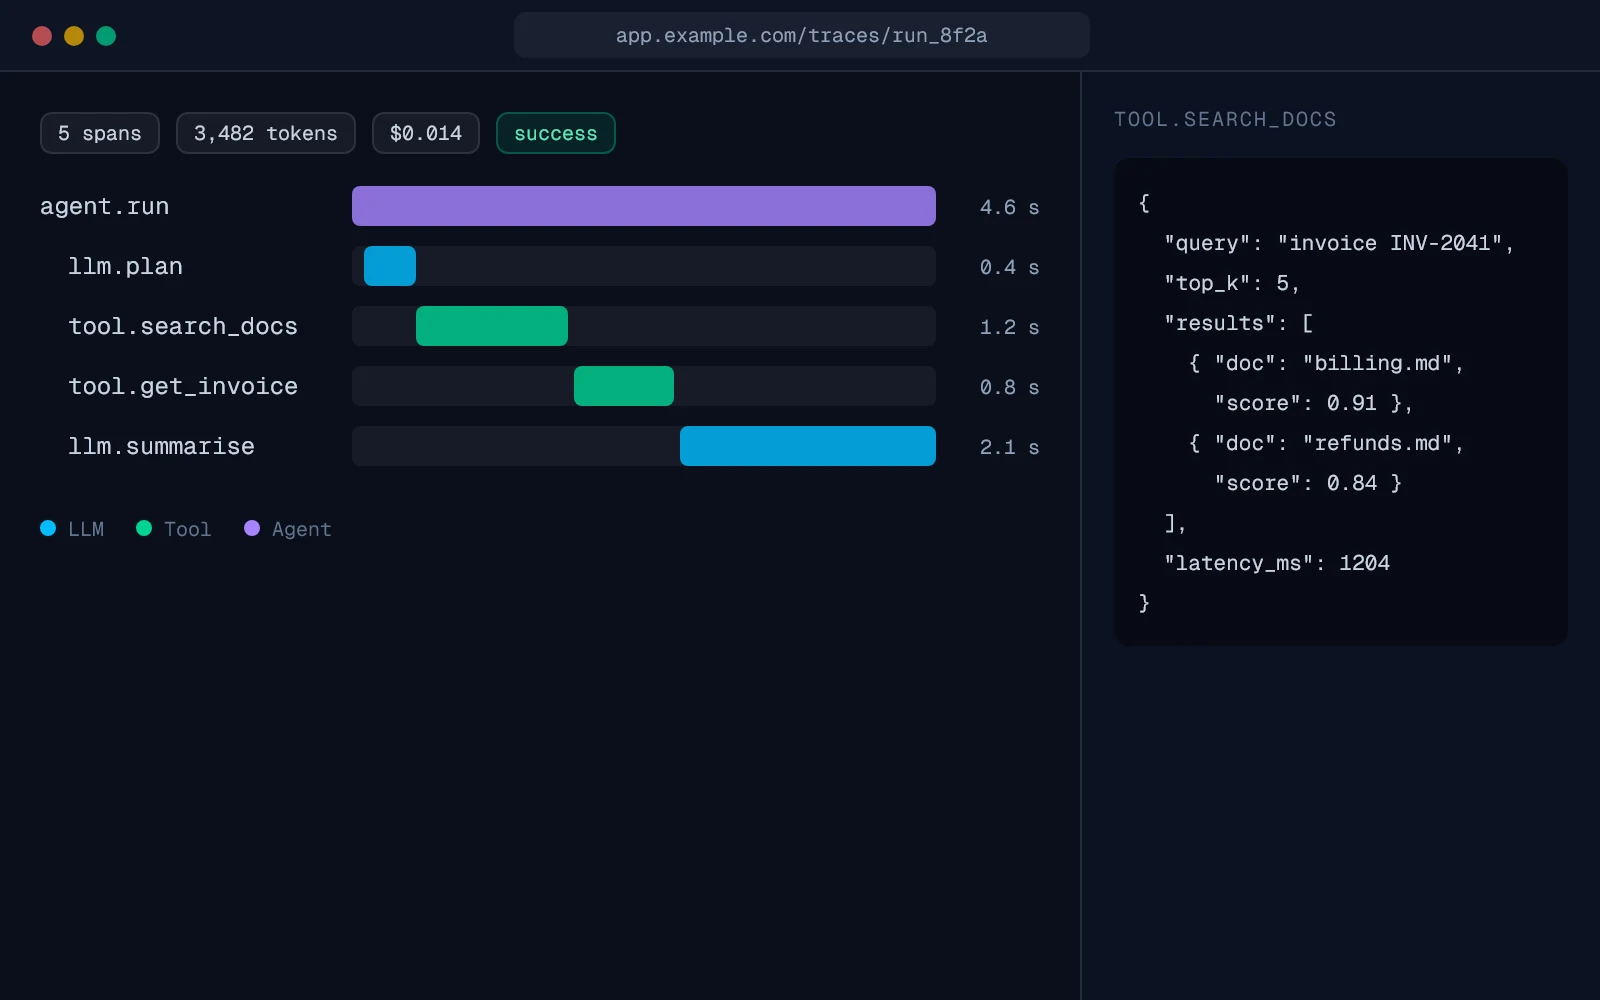
AgentTraceViewer
Timeline of tool calls, reasoning steps and token cost for debugging agent runs.
- Observability
- Timeline
- Tool use