 Featured
AI Interfaces4 min read
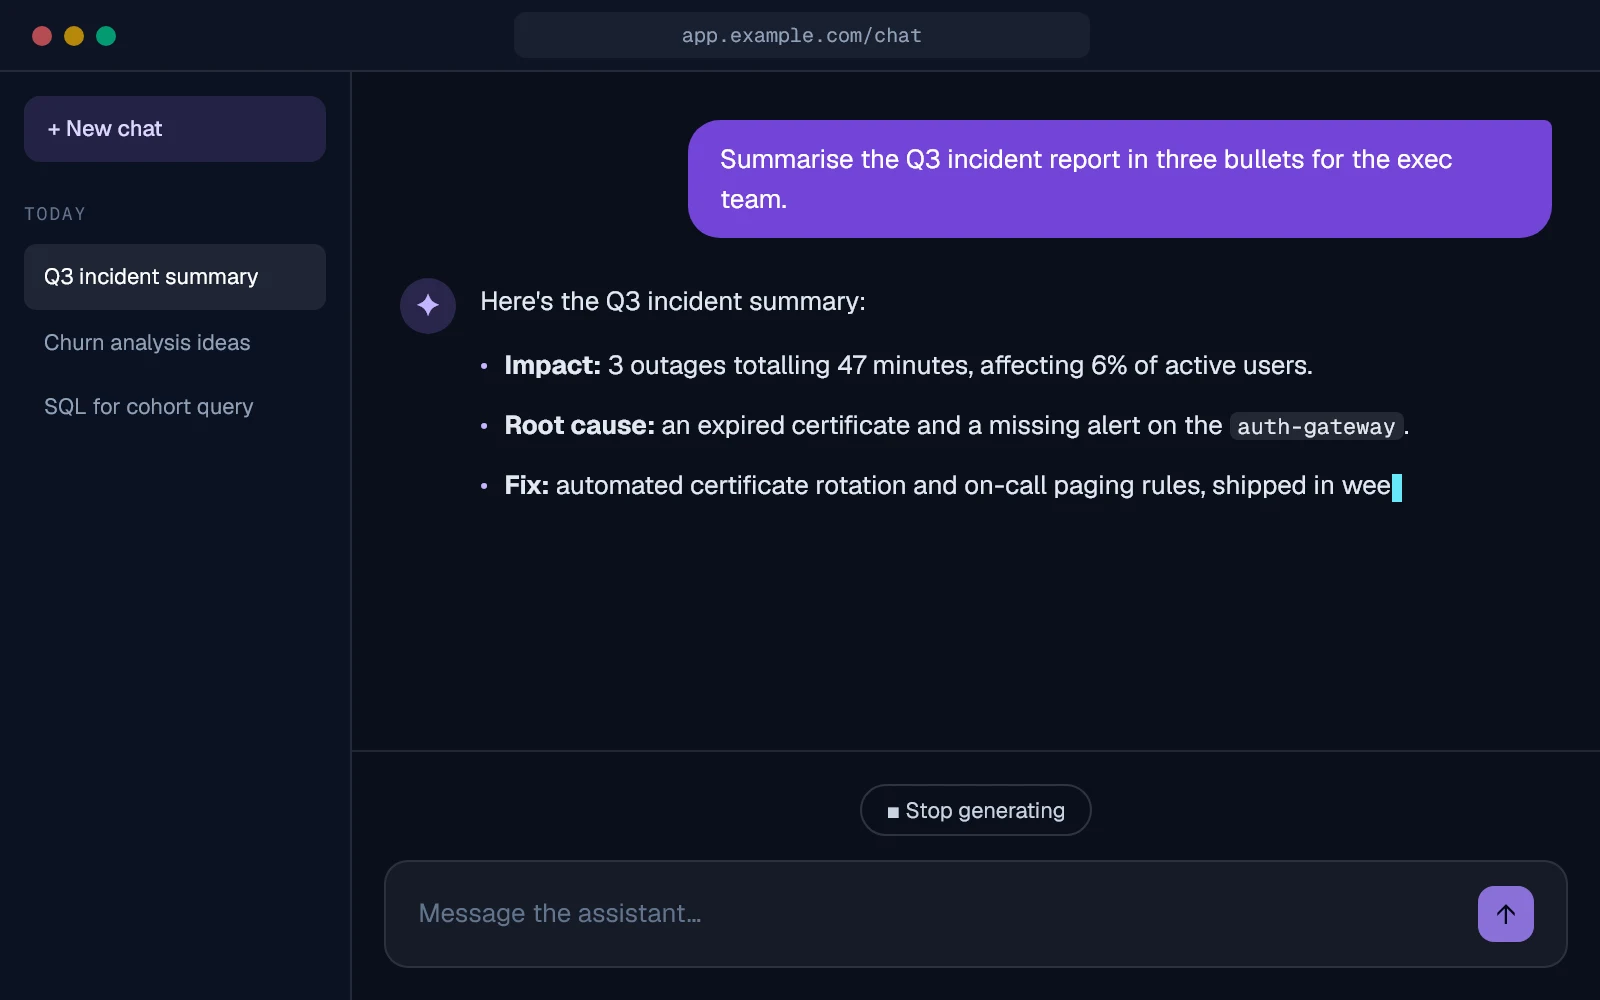
Building a streaming chat UI that doesn't jank
Token-by-token rendering, scroll behaviour and abort handling — the patterns that keep an LLM chat feeling instant.
- Streaming
- React 19
- UX
Read the note
Labs · research notes
Experiments, measurements and findings from building AI interfaces, RAG pipelines, accessibility and performance work. Each note records what was tried, what was measured and what held up.
FeaturedToken-by-token rendering, scroll behaviour and abort handling — the patterns that keep an LLM chat feeling instant.
Filter by the topic you care about.
Showing 6 posts
Token-by-token rendering, scroll behaviour and abort handling — the patterns that keep an LLM chat feeling instant.
How to ground RAG answers and link every claim back to the exact source passage.
What the spec says, what screen readers really announce, and the bugs that slip through.
Windowing, memoisation and measuring with the profiler — a practical guide to fast data grids.
Combining BM25 with vector search and reranking, and how to tell which one is winning.
Polite vs assertive, toasts, async results — making dynamic UI usable with a screen reader.